11 Cleaning changes the preferred sequence
Problem 11 | Batch Production with Sequence-Dependent Cleaning | Level 2: Model extension
11.1 Problem Statement
Four nonpreemptive batches must be processed on one vessel. The vessel is clean and available at time zero. A release time is the earliest processing start, not the earliest cleaning start. Cleaning may occur while the next batch awaits release. Initial and final cleaning times are zero.
| Job | Processing time (h) | Release (h) | Due time (h) | Tardiness charge (USD/h) |
|---|---|---|---|---|
| A1 | 2 | 0 | 6 | 4 |
| A2 | 3 | 2 | 12 | 2 |
| B1 | 2 | 1 | 7 | 5 |
| C1 | 4 | 0 | 14 | 1 |
Cleaning times depend on product family, denoted by the first letter of the job name:
| From / to | A | B | C |
|---|---|---|---|
| A | 0 | 1 | 2 |
| B | 3 | 0 | 1 |
| C | 1 | 2 | 0 |
All cleaning times are in hours. Normal shift length is 12 h. For the reference models, processing starts lie between 0 and 30 h and the final completion time between 0 and 40 h.
Your task. Include the directed cleaning-time matrix and again minimize makespan. Compare the result with the idealized schedule.
11.1.1 Before you code
Is the setup between A and B symmetric? Why must cleaning be charged only between immediate neighbors rather than every ordered pair?
11.1.2 Deliverables
- Define decision variables, units, objective, and constraints. State which data and assumptions are fixed.
- Predict one feature of the solution and explain why it should occur.
- Build and solve a Pyomo model. Check balances and bounds independently.
- Interpret the result and investigate the follow-up question below. For an open-ended challenge, state and defend your chosen policy separately from the reference solution.
11.2 Model Formulation
Let \(x_{ij}=1\) if job \(j\) immediately follows \(i\), with dummy nodes start and end. Let \(s_j\) be processing start and \(C_{max}\) final completion. Each job has exactly one predecessor and one successor; start has one outgoing arc and end one incoming arc. There is no direct start-end arc.
For job-to-job arcs, \[s_j\ge s_i+p_i+t_{ij}-M(1-x_{ij}),\qquad s_j\ge r_j.\] For job-to-end arcs, replace \(s_j\) by \(C_{max}\) and set cleaning to zero. Use \(M=50\) h. This is sufficient because starts are at most 30 h, processing at most 4 h, and cleaning at most 3 h; a deactivated inequality is redundant. Positive processing times rule out disconnected directed cycles: summing the time inequalities around a cycle would imply a strictly positive duration is at most zero.
Retain the time inequalities using the specified \(t_{ij}\). The arc formulation is essential: a pairwise before/after indicator alone does not identify which batches are adjacent. The reference objective remains \(\min C_{max}\), so late deliveries are still not penalized.
11.3 Pyomo Implementation
The code below is the model-building portion of models/scheduling.py. The level argument selects this problem’s assumptions. Run the complete module from the source bundle to reproduce the solution, including its independent checks:
~/.venvs/optim/bin/python -m models.scheduling 2"""Single-vessel sequencing with release times and directed cleaning."""
import itertools
import pyomo.environ as pyo
from models.common import value
JOBS = ["A1", "A2", "B1", "C1"]
DURATION = {"A1": 2, "A2": 3, "B1": 2, "C1": 4} # h
RELEASE = {"A1": 0, "A2": 2, "B1": 1, "C1": 0}
DUE = {"A1": 6, "A2": 12, "B1": 7, "C1": 14}
WEIGHT = {"A1": 4, "A2": 2, "B1": 5, "C1": 1} # USD/(h of tardiness)
CLEAN = {
("A", "B"): 1,
("A", "C"): 2,
("B", "A"): 3,
("B", "C"): 1,
("C", "A"): 1,
("C", "B"): 2,
}
def cleaning(i, j, level):
return 0 if level == 1 or i == "start" or j == "end" else CLEAN.get((i[0], j[0]), 0)
def build(level):
arcs = [
(i, j)
for i in ["start"] + JOBS
for j in JOBS + ["end"]
if i != j and (i, j) != ("start", "end")
]
m = pyo.ConcreteModel(name="Batch vessel schedule")
m.J = pyo.Set(initialize=JOBS)
m.A = pyo.Set(initialize=arcs, dimen=2)
m.x = pyo.Var(m.A, domain=pyo.Binary)
m.s = pyo.Var(m.J, bounds=(0, 30))
m.finish = pyo.Var(bounds=(0, 40))
m.out = pyo.Constraint(
["start"] + JOBS,
rule=lambda m, i: sum(m.x[i, j] for a, j in m.A if a == i) == 1,
)
m.inc = pyo.Constraint(
JOBS + ["end"], rule=lambda m, j: sum(m.x[i, j] for i, b in m.A if b == j) == 1
)
m.release = pyo.Constraint(m.J, rule=lambda m, j: m.s[j] >= RELEASE[j])
m.time = pyo.ConstraintList()
for i, j in arcs:
if i == "start":
continue
target = m.finish if j == "end" else m.s[j]
m.time.add(
target
>= m.s[i] + DURATION[i] + cleaning(i, j, level) - 50 * (1 - m.x[i, j])
)
m.tardy = pyo.Var(m.J, domain=pyo.NonNegativeReals)
m.late = pyo.Constraint(
m.J, rule=lambda m, j: m.tardy[j] >= m.s[j] + DURATION[j] - DUE[j]
)
m.overtime = pyo.Var(domain=pyo.NonNegativeReals)
m.over = pyo.Constraint(expr=m.overtime >= m.finish - 12)
objective = (
m.finish
if level < 3
else sum(WEIGHT[j] * m.tardy[j] for j in m.J) + 0.5 * m.overtime
)
m.obj = pyo.Objective(expr=objective)
return mThe common solve function calls appsi_highs, checks optimal termination before loading a solution, and checks constraint residuals, bounds, and integer domains. After building the model, use:
from models.common import solve
m = solve(build(2))
11.4 Optimal Solution
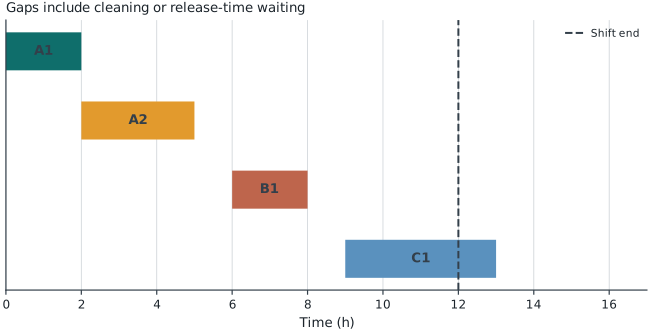
The reference objective is 13.0000 h. This value is optimal for the explicitly stated model and data.
| Job | Start (h) | Finish (h) | Tardiness (h) |
|---|---|---|---|
| A1 | -0.0000 | 2.0000 | 0.0000 |
| A2 | 2.0000 | 5.0000 | 0.0000 |
| B1 | 6.0000 | 8.0000 | 1.0000 |
| C1 | 9.0000 | 13.0000 | 0.0000 |
| Quantity | Value |
|---|---|
| Sequence | A1 > A2 > B1 > C1 |
| Makespan (h) | 13.0000 |
| Cleaning (h) | 2.0000 |
11.4.1 Check your solution
Independently total processing, cleaning, and idle time on the chosen path. Compare with exhaustive permutation enumeration.
The automated residual, bound, and integrality audit passed with a maximum violation of 1.69e-14 in model units. Domain-specific checks passed. Model units differ across equations, so this numerical audit does not replace dimensional analysis.
11.5 Brief Discussion
One optimal sequence is A1 > A2 > B1 > C1, with makespan 13.00 h and 2.00 h of cleaning. The makespan is 2.00 h above the idealized no-cleaning lower bound. Equivalent optimal sequences may differ across solver versions; the objective and feasibility checks are the comparison criteria.
11.5.1 Extension to investigate
Add a restriction forbidding a direct transition from B to A. Determine whether the optimal makespan changes.